here you goThings I’ve made, read and saved — shared here.

Archive

9,668 entries: 87 from X, 8,928 from Pinboard, saved 1998 to 2026.

Browse by tag, site, author, folder or language

Tags

Sites

Authors

Folders

Languages

Showing 1,351–1,400 of 9,668

2024

Charlie Munger

Here are 10 thoughts from Charlie Munger

  1. Why ignoring experts is smart: "You must have the confidence to override people with more credentials whose cognition is impaired by incentive-caused bias.”

  2. Intensity wins: "Passion is more important than brainpower."

  3. The Roman System: "An example of a really responsible system is the system the Romans used when they built an arch. The guy who created the arch stood under it as the scaffolding was removed. It’s like packing your own parachute."

  4. Just because you’ve had one misfortune doesn’t mean you should let it compound into two: "You should never, when faced with one unbelievable tragedy, let one tragedy increase into two or three because of a failure of will."

  5. A forest that does not clear its deadwood with small fires will, one day, suffer a giant uncontrollable fire. Brains must clear their deadwood too. Munger: "Rapid destruction of your ideas when the time is right is one of the most valuable qualities you can acquire."

  6. Your gadgets are more deadweight than they are your engines: "Look at this generation, with all of its electronic devices and multitasking. I will confidently predict less success than Warren, who just focused on reading. If you want wisdom, you’ll get it sitting on your ass. That’s the way it comes."

  7. Pure thinking (not interrupted by meetings and other "tasks") is a productivity hack the world is sleeping on: "We insist on a lot of time being available almost every day to just sit and think. That is very uncommon in American business. We read and think."

  8. There's a strange taboo against reading. Elon Musk has said in the new Walter Isaacson book that his parents were always trying to get him to read less. Charlie Munger said his kids laugh at his reading habit, calling him a book with two legs sticking out.

  9. This mockery is misplaced. Munger: "In my whole life, I have known no wise people who didn't read all the time - none, zero." Without books, travel, and aggressive independent thinking, there is no way for you to leave the intellectual context you were born in.

  10. Only high-trust tribes build civilization: "The highest form that civilization can reach is a seamless web of deserved trust—not much procedure, just totally reliable people correctly trusting one another."

Mungerisms

via X/aschwags3

  1. Write your obituary and live it backwards.
  2. The really big opportunities in life will be very few. So when you find a lollapalooza, and you can see it, don't hang back like a timid rabbit. Step boldly and grab it. And don't do it small.
  3. Learn the big ideas in all the disciplines. Pay no heed to sectoral boundaries. And cross-apply like crazy.
  4. Whenever you think something or some person is ruining your life, it's you. A victimization mentality is so debilitating
  5. A lot of success in life and business comes from knowing what you want to avoid: early death, a bad marriage
  6. Go to sleep each night a little less stupid than you were when you woke up.
  7. Never, ever, think about something else when you should be thinking about the power of incentives
  8. Assume life will be really tough, and then ask if you can handle it. If the answer is yes, you've won.
  9. Do what you like and are good at. Three rules for a career: Don't sell anything you wouldn't buy yourself; Don't work for anyone you don't respect and admire; Work only with people you enjoy
  10. It is remarkable how much long-term advantage people like us have gotten by trying to be consistently not stupid.
notes#person

Building Multimodal Search and RAG

Course notes from Building Multimodal Search and RAG about Multimodal Learning.

  • Instructor: Sebastian Witalec, head of developer relations at Weaviate,
  • human's learn multi-modally
  • human's foundational knowledge is built using multi-modal interaction with the world and not via language.
  • multi-modal embedding models produce a joint embedding space that understand all your modalities (e.g.: text, video, audio, picture).
  • Training:
    • start with specialist models
    • unify these models
    • the vectors that they generate are going to be similar
    • Models are unified using a process called contrastive representative learning.
      • CRL is a general purpose process that can be used to train any embedding model.
      • create one unified vector space representation for multiple modalities
        • by giving positive and negative examples, we train the models to pull closer vectors together for similar examples. and push away dissimilar examples
        • Anchor point
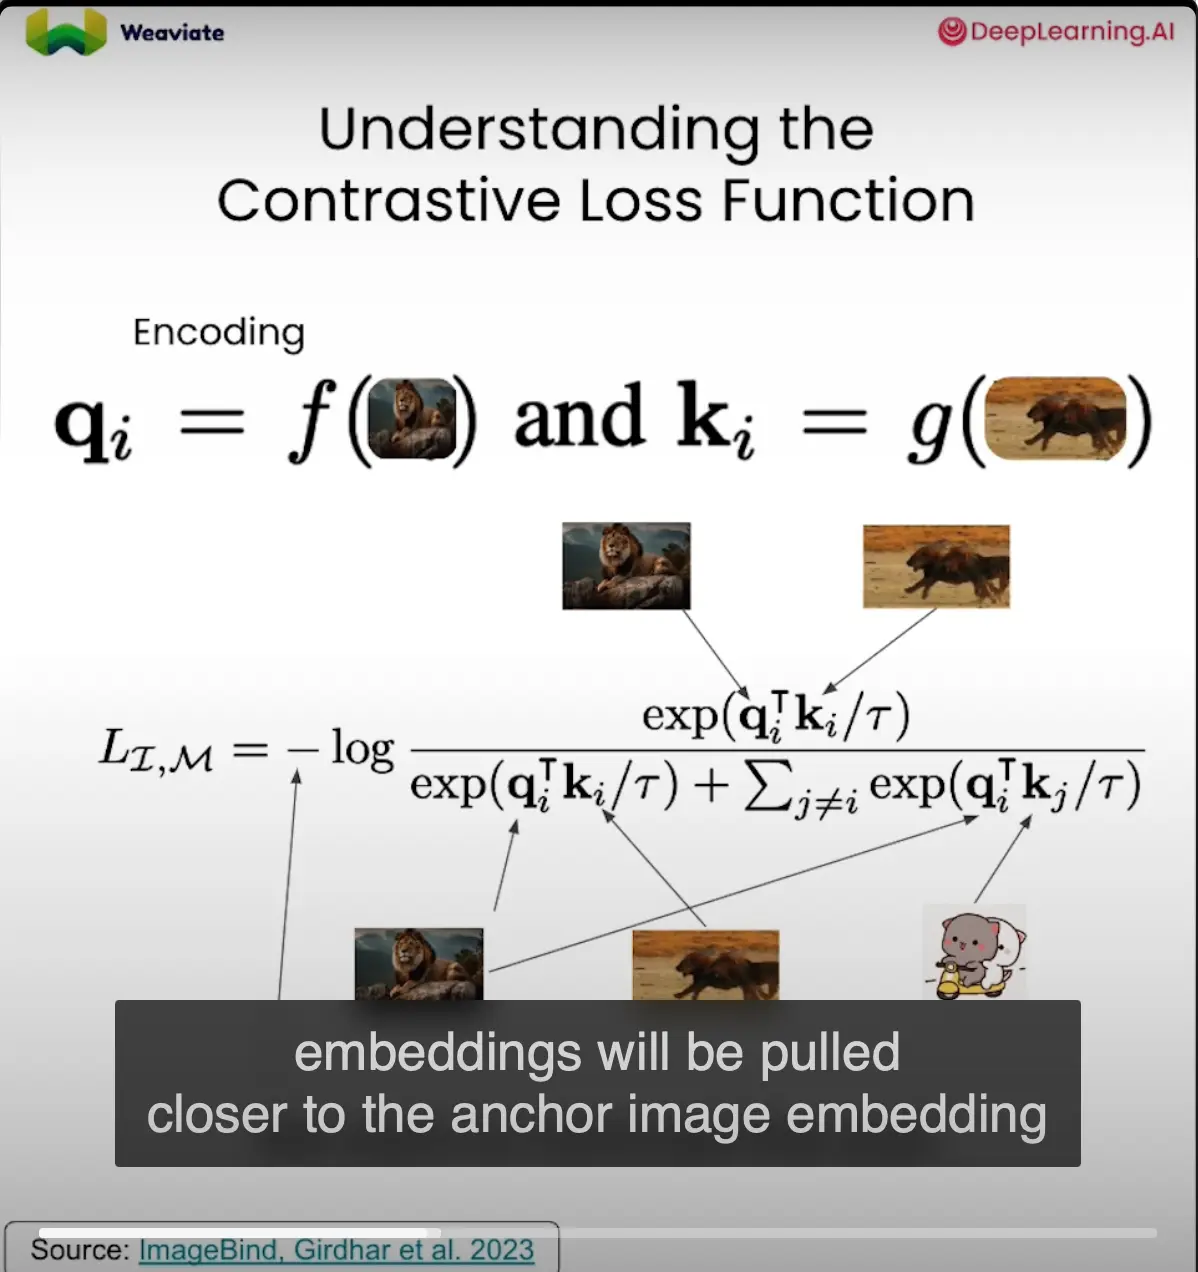
        • The pushing pulling process is achieved with the contrastive loss function.
          • encode the anchor and the (+ve and -ve ) examples into vector embeddings.
          • calculate the distance between the anchor and the examples.
          • minimize the distance between the positive example and maximize the negative example during the training process.
          • in multimodal learning, the examples can be from different modalities.
          • Minimize the loss... (Girdhar et al. 2023)


[via](https://learn.deeplearning.ai/courses/building-multimodal-search-and-rag/lesson/2/overview-of-multimodality)

References

notes#course#deep-learning

github

Discovering Small GitHub Projects for Contributing to FOSS; interesting use of github search.

Tools related to github:

notes#git#github

PDF

Stering-PDf - Locally hosted web application that allows you to perform various operations on PDF files. See also PDFPea - Edit PDFs Online Securely and Free | Privacy-First PDF Editor

Dangerzone - Convert potentially dangerous documents into safe PDFs

ExifTool by Phil Harvey -Read, Write and Edit Meta Information!

QPDF - A Content-Preserving PDF Transformation System

Some of these above were found via


small script to cleanup pdfs in general (reducing their size as well), via.

pdftops -paper A4 -expand -level3 file.pdf
ps2pdf14 -dEmbedAllFonts=true          \
    -dUseFlateCompression=true           \
    -dOptimize=true                      \
    -dProcessColorModel=/DeviceRGB       \
    -r72                                 \
    -dDownsampleGrayImages=true          \
    -dGrayImageResolution=150            \
    -dAutoFilterGrayImages=false         \
    -dGrayImageDownsampleType=/Bicubic   \
    -dDownsampleMonoImages=true          \
    -dMonoImageResolution=150            \
    -dMonoImageDownsampleType=/Subsample \
    -dDownsampleColorImages=true         \
    -dColorImageResolution=150           \
    -dAutoFilterColorImages=false        \
    -dColorImageDownsampleType=/Bicubic  \
    -dPDFSETTINGS=/ebook                 \
    -dNOSAFER                            \
    -dALLOWPSTRANSPARENCY                \
    -dShowAnnots=false                   \
     file.pdf file.pdf

notes#pdf

Durable Execution

Open Source Durable Execution | Temporal Technologies

Durable Execution is a development abstraction that preserves complete application state so that upon host or software failure it can seamlessly migrate execution to another machine.

Temporal is an open-source implementation of Durable Execution created by the originators of the abstraction. See examples page


Restate a system for workflows-as-code (durable execution). With SDKs in JS | Java | Kotlin and a lightweight runtime built in Rust/Tokio. Is licensed BSL. See HN Threat

  • Restate's runtime is a single binary, self-contained, no dependencies aside from a durable disk. It contains basically a lightweight integrated version of a durable log, workflow state machine, state storage, etc. That makes it very compact and easy to run both on a laptop and a server.
  • Restate implements durable execution not only for workflows, but the core building block is durable RPC handlers (or event handler). It adds a few concepts on top of durable execution, like virtual objects (turn RPC handlers into virtual actors), durable communication, and durable promises. Here are more details: Programming model.

dbos-inc/dbos-transact-py: Ultra-Lightweight Durable Execution in Python

Durable execution means your program is resilient to any failure. If it is ever interrupted or crashes, all your workflows will automatically resume from the last completed step.

Under the hood, DBOS Transact works by storing your program's execution state (which workflows are currently executing and which steps they've completed) in a Postgres database. So all you need to use it is a Postgres database to connect to—there's no need for a "workflow server."

notes

Vahaduo

vahaduo.github.io

A collection of tools for admixture and PCA analysis based on multivariate input data. Run models, create interactive 2D and 3D graphs, and explore the genetic diversity of ancient and modern human populations.

Django

Django from first principles

Static site generator for Django - Django Distill

While making https://thesummarist.net, I came across https://django-distill.com, which is THE BEST way to create static sites, bar none. You just make a standard, dynamic Django site, then you run a command and boom! It's static. I love it. -- via Stravos

Django SQLite Production Config

# yourproject/settings.py
DATABASES = {
    "default": {
        "ENGINE": "django.db.backends.sqlite3",
        "OPTIONS": {
            "transaction_mode": "IMMEDIATE",
            "timeout": 5,  # seconds
            "init_command": """
                PRAGMA journal_mode=WAL;
                PRAGMA synchronous=NORMAL;
                PRAGMA mmap_size = 134217728;
                PRAGMA journal_size_limit = 27103364;
                PRAGMA cache_size=2000;
            """,
        },
    }
}

notes#django#python

Sixteen boons

Blessing the newly weds - "Live a long life acquiring 16 boons"

Via "Pathinarum Petru Peru Vazhvu Vazhga" 16 boons - "thudhi vaani veeram visayam sandhaanam thunivu dhanam madhi dhaaniyam saubaaggiyam bogam - arivu azhagu pudhidhaam perumai aram kulam novagal pun vayadhu"

  • thudhi = fame
  • vaani = education
  • veeram = courage
  • visayam = success
  • sandhaanam (santānam) = progeny
  • thunivu = daring
  • dhanam = finance
  • madhidhaaniyam = valued grain(abundance of food)
  • saubaaggiyam (saubhāgyam) = well-being
  • bogam (bhōgam) = enjoyment of pleasures
  • arivu = wisdom
  • azhagu = beauty

(IAST notes in bracket by me).

notes

Python Frontend Frameworks

Write complete web applications in Python without writing javascript. There are a large class of problems for which this is an excellent solution, without having to dip into the javascript tarpit.

The advantage of something like this over using templates is that you can think of "widgets" vs "templates".

Some frameworks are:

Reflex (formerly known as pynecone). Uses FastAPI + React.

NiceGUI. Uses FastAPI + Vue.js + Quasar, tailwind.

Pydantic/FastUI. Uses React. still early in development.

Gradio -- "Build & Share Delightful Machine Learning Apps"

notes#javascript#python#web

The Arc Product-Market Fit Framework | Sequoia Capital

sequoiacap.com

Finding product-market fit is the central quest of every early-stage startup. As we have seen over years of partnering with companies before they reached PMF, there are many ways of thinking about and approaching this quest. We walk founders through the following framework during Arc, our company-building immersion for pre-seed and seed stage companies. Rather than diagnosing whether you have product-market fit, this framework outlines three distinct archetypes of PMF which help you understand your product’s place in the market and determine how your company operates.

Google Gemini

Gemini is Google's AI/llm model introduced in Dec '23 - Introducing Gemini: Google’s most capable AI model yet

In Apr 2024, they announced Gemini 1.5 Pro - Gemini 1.5 Pro Now Available in 180+ Countries; With Native Audio Understanding, System Instructions, JSON Mode and More - Google for Developers understands audio, uses unlimited files, acts on your commands, and lets devs build things with JSON mode. 1 million token context window. Ask Gemini about ten books of text, 9 hours of audio or a movie worth of video frames.

notes#gemini#google#llm

SWE Agent

Devin from Cognitive AI made waves when it came out in March 2024.

There are follow-on developments since then.

References

notes#llm#swe-agent

terraform

Winglang

This is still in development, but interesting to keep an eye on, in light of Terraform/OpenTOFU kerfuffle. Written by the author of AWS CDK.

Cloud applications are fundamentally different from applications that run on a single machine - they are distributed systems that rely on cloud infrastructure to achieve their goals.

In order to be able to express both infrastructure and application logic in a safe and unified programming model, Winglang has two execution phases: preflight for infrastructure definitions and inflight for runtime code. Preflight code is executed during compilation and produces the infrastructure configuration for your app (e.g. Terraform, CloudFormation, etc). Inflight code is compiled into JavaScript and executed within cloud compute platforms in Node.js environments.


OpenTaco – Terraform automation that feels invisible "Raise a PR and OpenTaco runs terraform plan automatically, posting the output as a comment. Approve and merge, it applies. State is versioned with rollback built in. Drift is detected on a schedule and filed as issues in GitHub. Terraform runs natively in your CI. Your cloud credentials never leave your environment. No third-party compute, no secrets shared with a SaaS."

notes#terraform

Fine Tuning

Why fine tune?

  • Greater Accuracy -- By tailoring the model to specific use cases and industries, it can better understand and generate contextually relevant responses.
  • Improve Efficiency -- Fine-tuning streamlines performance by reducing token usage and condensing the effectiveness of a larger model into a smaller, more efficient one.

Fine-tuning tailors the LLM's weights to specific domains and tasks, improving performance on long-term challenges. via

Tutorials

Fine-Tuning LLMs: A Guide With Examples ; and How to Fine Tune GPT 3.5

Notes

some good experience shared here: https://x.com/MaximeRivest/status/1895315348544483633 in response to https://x.com/simonw/status/1895301139819860202

gemma-3-270m might be a good model to finetune; should be possible to do it on my MBP.

notes#llm

cohere

Cohere -- an AI SaaS platform. It has - Command Embed and Rerank models. Cohere also has Fine Tuning.

Command R+

Announced on Apr 4, 2024, where Command R+ is an enterprise-grade Large Language Model (LLM) optimized for Retrieval Augmented Generation (RAG) and tool use. This multilingual model, which excels in 10 key languages, is available on Cohere's Playground and Azure, with plans for expansion to other platforms. Command R+ is designed to be more accurate and relevant for specific uses, leveraging a 128k-token context window.

How to use Command R+, a thread on twitter.

Adaptive RAG with Cohere's Command R+ by. LangChainAI.

Building adaptive RAG from scratch with Command-R - YouTube


Cohere North Mini Code 1.0

Use it with pi.dev

uv run mlx_vlm.server --model CohereLabs/North-Mini-Code-1.0
pi --provider mlx-lm --model CohereLabs/North-Mini-Code-1.0

notes#cohere#saas

Text Embedding

See also: llm

via ➡️ Text embedding models represent natural language as dense vectors, positioning semantically similar text near each other within the embedding space. Or in simple terms, text embedding models are like translators for computers. They take text and convert it into numbers in a way the computer can understand.

The numerical representations, also known as embeddings, capture semantic information about the words or sentences in the text. By allowing computers to process natural language, these embeddings are used to carry out a wide range of downstream tasks including document retrieval, sentence similarity, classification, and clustering.

An intuitive introduction to text embeddings - Stack Overflow blog

We can frame a lot of useful tasks in terms of text similarity.

  • Search: How similar is a query to a document in your database?
  • Spam filtering: How close is an email to examples of spam?
  • Content moderation: How close is a social media message to known examples of abuse?
  • Conversational agent: Which examples of known intents are closest to the user’s message?

Effective and fast text embedding methods transform textual input into a numeric form, which allows models such as GPT-4 to process immense volumes of data and show a remarkable level of natural language understanding.

A deep, intuitive understanding of text embeddings can help you follow the advances of these models, letting you effectively incorporate them into your own systems without combing through the technical specs of each new improvement as it emerges.


The Beginner’s Guide to Text Embeddings | deepset

The foundational technology for modern-day NLP is the text embedding, also known as a “vector”: without word and sentence vectors, there would be no cutting-edge translation apps, no automated summaries, and no semantic search engines as we know them. What’s more, embeddings can be used to represent other data types as well, like images and audio files.

Embeddings 101: The foundation of large language models

Embeddings are underrated

What embeddings offer to technical writers is the ability to discover connections between texts at previously impossible scales.

Gecko

Gecko is an text embedding model from Google, it's 768-dim vectors being competitive with models that have 7x more parameters and 5x larger embeddings. (Lee et al. 2024). Results: Gecko is best-in-class for models with BERT-sized embeddings, and due to its support for Matryoshka Learning, it outperforms all such models with just 256 dimensions. Furthermore, when using all 768 dimensions, it competes directly with titans such as E5-Mistral and GritLM, which have 7B parameters (vs Gecko's 1.2B) and 4096 embedding dimensions. Impressive! An interesting finding that gives credit to the use of synthetic data can be seen in the last row, where the model trained exclusively on LLM-generated data (instead of the typical mixture that includes MTEB datasets) remains quite performant for its size.

NOTE: likely not usable right now since the model weights are not available.

References

notes#llm