# LLM
- Page: https://shared.btbytes.com/p/llm
- Date: 2023-03-17
- Tags: llm, chatgpt, deep-learning
## Introductory Materials
[Generative AI exists because of the transformer](https://ig.ft.com/generative-ai/) -- A visual story from Financial Times; Sept 2023.
[Large language models, explained with a minimum of math and jargon](https://www.understandingai.org/p/large-language-models-explained-with)
[A High-level Overview of Large Language Models - Borealis AI](https://www.borealisai.com/research-blogs/a-high-level-overview-of-large-language-models/)
[Tiny LLM - LLM Serving in a Week](https://skyzh.github.io/tiny-llm/preface.html) -- uses MLX (on MacOS) to ... implement an LLM serving project from scratch -- with only matrix manipulations APIs, so that I can understand what it takes to load those LLM model parameters and do the math magic to generate text.
## Books
- [Language Models in Plain English](https://drive.google.com/file/d/19RGCipH7oV7qfY5V-GscprN7HCRaR03q/view) by Austin Eovito and Marina Danilevsky published by IBM on O'Reilly.
- [Transformers & Large Language Models | Super Study Guide](https://superstudy.guide/transformers-large-language-models/)
## Study Guides
-[Mastering LLMs](https://parlance-labs.com/education/) workshop. See [Takeaways from Mastering LLMs Course](https://swaroopch.com/blog/mastering-llms/) from SwaroopCH.
- [The Novice's LLM Training Guide](https://rentry.org/llm-training#the-basics); [copy](https://gist.github.com/btbytes/cf845f9ade1cb34348110c14c8c49cea)
- [Normcore LLM Reads](https://gist.github.com/veekaybee/be375ab33085102f9027853128dc5f0e) by Vicki Boykis
- [A Hackers' Guide to Language Models - YouTube](https://www.youtube.com/watch?v=jkrNMKz9pWU) by jeremy-howard
- [Transformer Math 101 | EleutherAI Blog](https://blog.eleuther.ai/transformer-math/)
- [Lil'Log](https://lilianweng.github.io/); lilian weng's blog
- [The maths you need to start understanding LLMs :: Giles' blog](https://www.gilesthomas.com/2025/09/maths-for-llms)
## Blogs and websites
- [Lil'Log](https://lilianweng.github.io/) Hi, this is Lilian. I’m documenting my learning notes in this blog. Other than writing a ML blog, I’m leading Applied Research at OpenAI on the side.
- Finbarr Timbers -- eg: [Five years of GPT progress](https://finbarr.ca/five-years-of-gpt-progress/)
- [Vespa Blog](https://blog.vespa.ai/index.html)
- [Lycee.AI blog](https://www.lycee.ai/blog)
- [Notes on AI](https://notesonai.com/notes+on+ai); someone's [obsidian](https://shared.btbytes.com/p/obsidian) notes on AI.
## Papers
- Collection of LLM papers: [GitHub - horseee/Awesome-Efficient-LLM: A curated list for Efficient Large Language Models](https://github.com/horseee/Awesome-Efficient-LLM/) by [Xinyin Ma](https://horseee.github.io/).
- [Microsoft LMOps](https://github.com/microsoft/LMOps/tree/main) -- a research initiative on fundamental research and technology for building AI products w/ foundation models, especially on the general technology for enabling AI capabilities w/ LLMs and Generative AI models.
- Sparks of Artificial General Intelligence: Early experiments with GPT-4. (2023) [PDF](https://arxiv.org/pdf/2303.12712.pdf) -- (Bubeck et al. 2023)
- [SeamlessM4T—Massively Multilingual & Multimodal Machine Translation | Meta AI Research](https://ai.meta.com/research/publications/seamless-m4t/) -- ([Barrault et al. 2023](https://arxiv.org/abs/2308.11596))
- ([Brown et al. 2020](https://arxiv.org/abs/2005.14165))
## Videos
[An observation on Generalization - YouTube](https://www.youtube.com/watch?v=AKMuA_TVz3A) by Ilya Sutskever (OpenAI); Aug 14, 2023.
- Supervised Learning - precise mathematical condition under which learning should succeed, which is - *Low training error + more training data than "degrees of freedom" = low test error*
## Prompt Engineering
- [ChatGPT Prompt Engineering for Developers - DeepLearning.AI](https://www.deeplearning.ai/short-courses/chatgpt-prompt-engineering-for-developers/)
- [Prompt Engineering | Lil'Log](https://lilianweng.github.io/posts/2023-03-15-prompt-engineering/) -- "This post only focuses on prompt engineering for autoregressive language models, so nothing with Cloze tests, image generation or multimodality models."
- [Controllable Neural Text Generation | Lil'Log](https://lilianweng.github.io/posts/2021-01-02-controllable-text-generation/) -- "How to steer a powerful unconditioned language model? In this post, we will delve into several approaches for controlled content generation with an unconditioned langage model. For example, if we plan to use LM to generate reading materials for kids, we would like to guide the output stories to be safe, educational and easily understood by children."
- [Replacing my best friends with an LLM trained on 500,000 group chat messages](https://www.izzy.co/blogs/robo-boys.html)
- [microsoft/guidance: A guidance language for controlling large language models.](https://github.com/microsoft/guidance) Guidance programs allow you to interleave generation, prompting, and logical control into a single continuous flow matching how the language model actually processes the text.
## Models
See this page - [Models Table – Dr Alan D. Thompson – Life Architect](https://lifearchitect.ai/models-table/) for a visual representation of models, and a table of various attributes of models.
## Stuff you can run on your computer
[Everything I've learned so far about running local LLMs](https://nullprogram.com/blog/2024/11/10/); Nov 2024.
[smol-ai/developer: with 100k context windows on the way, it's now feasible for every dev to have their own smol developer](https://github.com/smol-ai/developer)
[How is LLaMa.cpp possible?](https://finbarr.ca/how-is-llama-cpp-possible/) how can we run `llama.cpp` on local machines when the expectation is that large models need expensive GPUS (eg: A100) to run
[Introducing Code Llama, a state-of-the-art large language model for coding](https://ai.meta.com/blog/code-llama-large-language-model-coding/) Code Llama is a code-specialized version of [Llama 2](https://ai.meta.com/llama/) that was created by further training Llama 2 on its code-specific datasets, sampling more data from that same dataset for longer. Essentially, Code Llama features enhanced coding capabilities, built on top of Llama 2. It can generate code, and natural language about code, from both code and natural language prompts (e.g., “Write me a function that outputs the fibonacci sequence.”) It can also be used for code completion and debugging. It supports many of the most popular languages being used today, including Python, C++, Java, PHP, Typescript (Javascript), C#, and Bash.
[Ask HN: Cheapest way to run local LLMs? | Hacker News](https://news.ycombinator.com/item?id=38425761)
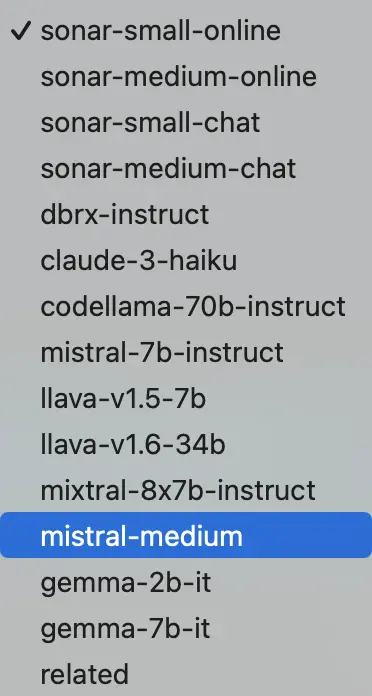
See also [Perplexity Labs](https://labs.perplexity.ai) where they have multiple models to try from
Perplexity labs models; Apr 2024
- Simon Willison's [simonw/language-models-on-the-command-line: Handout for a talk I gave about LLM and CLI tools](https://github.com/simonw/language-models-on-the-command-line)
- [gptscript-ai/gptscript: Build AI assistants that interact with your systems](https://github.com/gptscript-ai/gptscript) "GPTScript is a framework that allows Large Language Models (LLMs) to operate and interact with various systems. These systems can range from local executables to complex applications with OpenAPI schemas, SDK libraries, or any RAG-based solutions. GPTScript is designed to easily integrate any system, whether local or remote, with your LLM using just a few lines of prompts."
## LLMs in your language
[All languages are NOT created (tokenized) equal](http://web.archive.org/web/20230505200511/https://blog.yenniejun.com/p/all-languages-are-not-created-tokenized)
## Small Language Models
- (Eldan and Li 2023)
## Building LLMs
- [naklecha/llama3-from-scratch](https://github.com/naklecha/llama3-from-scratch) - llama3 implementation one matrix multiplication at a time
## Using LLMs
- [A Simple but Powerful Method to Analyze Online PDFs with Bing Chat - AI Demos](https://www.aidemos.info/a-simple-but-powerful-method-to-analyze-online-pdfs-with-bing-chat/)
- [What's new in Llama 2 & how to run it locally - AGI Sphere](https://agi-sphere.com/llama-2/); Aug 2023.
- [Fine-tune your own Llama 2 to replace GPT-3.5/4 | Hacker News](https://news.ycombinator.com/item?id=37484135)
> Fine-tuning has one huge advantage though: it is far more effective at guiding a model's behavior than prompting, so you can often get away with a _much_ smaller model. That gets you faster responses and lower inference costs. A fine-tuned Llama 7B model is 50x cheaper than GPT-3.5 on a per-token basis, and for many use cases can produce results that are as good or better!
> For example, classifying the 2M recipes at [https://huggingface.co/datasets/corbt/all-recipes](https://huggingface.co/datasets/corbt/all-recipes) with GPT-4 would cost $23k. Even with GPT-3.5 it would cost over $1k. The model we fine-tuned performs similarly to GPT-4 and costs just $19 to run over the entire dataset.
> [OpenBMB/ToolBench: An open platform for training, serving, and evaluating large language model for tool learning.](https://github.com/OpenBMB/ToolBench)
## Frameworks
[LlamaIndex 🦙 0.8.13](https://gpt-index.readthedocs.io/en/latest/)
[Haystack | Haystack](https://haystack.deepset.ai/) Open-source LLM framework to build production-ready applications.
> Use the latest LLMs: hosted models by OpenAI or Cohere, open-source LLMs, or other pre-trained models
> All tooling in one place: preprocessing, pipelines, agents & tools, prompts, evaluation and finetuning
> Choose your favorite database: Elasticsearch, OpenSearch, [Weaviate](https://www.btbytes.com/Weaviate), Pinecone, Qdrant, [Milvus](https://shared.btbytes.com/p/milvus) and more
> Scale to millions of documents: use Haystack's proven retrieval architecture
> Compare it to [LangChainAI](https://shared.btbytes.com/p/langchainai)
[GPT4All](https://gpt4all.io/index.html) A free-to-use, locally running, privacy-aware chatbot. **No GPU or internet required.**
[AI Proxy](https://x.com/ankrgyl/status/1726640887227388210)
> an AI proxy that lets you use a variety of providers (OpenAI, Anthropic, LLaMa2, Mistral, and others) behind a single interface w/ caching & API key management.
[MLC LLM](https://llm.mlc.ai/docs/) Machine Learning Compilation for Large Language Models (MLC LLM) is a high-performance universal deployment solution that allows native deployment of any large language models with native APIs with compiler acceleration. The mission of this project is to enable everyone to develop, optimize and deploy AI models natively on everyone’s devices with ML compilation techniques.
 [Project Overview of MLC LLM](http://web.archive.org/web/20230928124751/https://llm.mlc.ai/docs/get_started/project_overview.html)
## [Multimodal Learning](https://shared.btbytes.com/p/multimodal-learning)
todo
## Security
[OWASP | Top 10 for Large Language Models](https://llmtop10.com/)
## Abliteration
[Uncensor any LLM with abliteration](https://huggingface.co/blog/mlabonne/abliteration)
## Operational Issues
- [Why won’t Llama13B fit on my 4090_.pptx - Google Slides](https://docs.google.com/presentation/d/1lRsttm-FNTV6efX3EcVs8hZTEnTAXWUk/edit#slide=id.p3) by Mark Saroufim
## GGUF
> GGUF and GGML are file formats used for storing models for inference, especially in the context of language models like GPT
- [GGUF, the long way around](https://vickiboykis.com/2024/02/28/gguf-the-long-way-around/) by [Vicki Boykis](https://x.com/vboykis)
## Benchmarking LLMs
[LLM Benchmark Report for: NousResearch/Redmond-Puffin-13B](https://teknium1.github.io/LLM-Logbook/Reports/benchmark_report_NousResearch-Redmond-Puffin-13B_ShareGPT_September_25_2023.html)
## Linkdump
### 2023
- [Shoggoth](http://web.archive.org/web/20231106145639/https://shoggoth.network/explorer/docs) is a peer-to-peer, anonymous network for publishing and distributing open-source code, Machine Learning models, datasets, and research papers.
- [What We Know About LLMs (Primer)](https://willthompson.name/what-we-know-about-llms-primer) #primer
- [A comprehensive guide to running Llama 2 locally - Replicate – Replicate](https://replicate.com/blog/run-llama-locally); Jul 22, 2023.
- [PaLM2 Technical Report](https://ai.google/static/documents/palm2techreport.pdf) #pdf #google
- [dalai](https://cocktailpeanut.github.io/dalai/#/) -- Run LLaMA and Alpaca on your computer. ??
- [ggerganov/llama.cpp: Port of Facebook's LLaMA model in C/C++](https://github.com/ggerganov/llama.cpp)
- [LlamaIndex](https://github.com/jerryjliu/llama_index) - (GPT Index) is a project that provides a central interface to connect your LLM's with external data. see A complete chat app that transcribes audio in real-time, streams back a response from a language model, and synthesizes this response as natural-sounding speech. This repo is meant to serve as a starting point for your own language model-based apps, as well as a playground for experimentation.
- [A brief history of LLaMA models - AGI Sphere](https://agi-sphere.com/llama-models/)
- See [LangChainAI](https://shared.btbytes.com/p/langchainai)
- [ray-project/llm-numbers: Numbers every LLM developer should know](https://github.com/ray-project/llm-numbers); [via HN](https://news.ycombinator.com/item?id=35978864)
- [Beginner's guide to Llama models - AGI Sphere](https://agi-sphere.com/llama-guide/#What_is_Llama); Aug 2023.
- [The Mathematics of Training LLMs — with Quentin Anthony of Eleuther AI](https://www.latent.space/p/transformers-math#details)
- [Google Gemini Eats The World – Gemini Smashes GPT-4 By 5X, The GPU-Poors](https://www.semianalysis.com/p/google-gemini-eats-the-world-gemini); Aug 2023.
- [fast.ai - Can LLMs learn from a single example?](https://www.fast.ai/posts/2023-09-04-learning-jumps/)
### 2024
- [Stuff we figured out about AI in 2023](https://simonwillison.net/2023/Dec/31/ai-in-2023/)
- [Large language models use a surprisingly simple mechanism to retrieve some stored knowledge | MIT News | Massachusetts Institute of Technology](https://news.mit.edu/2024/large-language-models-use-surprisingly-simple-mechanism-retrieve-stored-knowledge-0325)
- Survey of Open source repos -- [What I learned from looking at 900 most popular open source AI tools](https://huyenchip.com/2024/03/14/ai-oss.html) ([via](https://x.com/zaph0id/status/1774652523715911881))
- ([Allen-Zhu and Li 2024](https://arxiv.org/abs/2404.05405))
- ([You et al. 2024](https://arxiv.org/abs/2404.05719))
- About BERT -- ([Geiping and Goldstein 2022](https://arxiv.org/abs/2212.14034)) -- [via](https://x.com/andersonbcdefg/status/1779049742783443061)
- ([Ma et al. 2024](https://arxiv.org/abs/2404.08801)); [github repo](https://github.com/dumpmemory/megalodon) (the repo link on paper wasn't working as of 2024-04-17).
- "phi-3-mini, a 3.8 billion parameter language model trained on 3.3 trillion tokens, whose overall performance, as measured by both academic benchmarks and internal testing, rivals that of models such as Mixtral 8x7B and GPT-3.5 (e.g., phi-3-mini achieves 69% on MMLU and 8.38 on MT-bench), despite being small enough to be deployed on a phone." ([Abdin et al. 2024](https://arxiv.org/abs/2404.14219)) (No code, or model was announced with the paper.)
- (@liu2024kan)
- ([Lin et al. 2024](https://arxiv.org/abs/2405.04674)) "Unstructured data formats account for over 80% of the data currently stored, and extracting value from such formats remains a considerable challenge.... ZenDB efficiently extracts semantic hierarchical structures from such templatized documents, and introduces a novel query engine that leverages these structures for accurate and cost-effective query execution. Users can impose a schema on their documents, and query it, all via SQL. Extensive experiments on three real-world document collections demonstrate ZenDB's benefits, achieving up to 30% cost savings compared to LLM-based baselines, while maintaining or improving accuracy, and surpassing RAG-based baselines by up to 61% in precision and 80% in recall, at a marginally higher cost."
- [Call to Build Open Multi-Modal Models for Personal Assistants | LAION](https://laion.ai/notes/open-gpt-4-o/)
- [What We Learned from a Year of Building with LLMs (Part I) – O’Reilly](https://www.oreilly.com/radar/what-we-learned-from-a-year-of-building-with-llms-part-i/)
- [What We Learned from a Year of Building with LLMs (Part II) – O’Reilly](https://www.oreilly.com/radar/what-we-learned-from-a-year-of-building-with-llms-part-ii/)
- [ARC Prize](https://arcprize.org/blog/launch)
- ([Chollet 2019](https://arxiv.org/abs/1911.01547)) by François Chollet.
- > "To make deliberate progress towards more intelligent and more human-like artificial systems, we need to be following an appropriate feedback signal: we need to be able to define and evaluate intelligence in a way that enables comparisons between two systems, as well as comparisons with humans."
- > "We then articulate a new formal definition of intelligence based on Algorithmic Information Theory, describing intelligence as skill-acquisition efficiency and highlighting the concepts of scope, generalization difficulty, priors, and experience, as critical pieces to be accounted for in characterizing intelligent systems."
- ([Ren et al. 2024](https://arxiv.org/abs/2406.07522))
## 2026
## References
- [Meta Reference - letsbuild.ai](https://letsbuild.ai)
- [Keeping up with AGI](https://docs.google.com/document/u/5/d/e/2PACX-1vQD8IlBotGdBxp3BnXkSjk8bNZlPV_0EH9ZA6wHd5dNf-BLSiwXUinvgv8ZoBEnNyTCF-chWO30NRw0/pub) reading list by [cto_junior](https://x.com/cto_junior).
- [LLM Course](https://github.com/mlabonne/llm-course) by [mlabonne](https://mlabonne.github.io/blog/)
----
See also: [Multimodal Learning](https://shared.btbytes.com/p/multimodal-learning), [Multi Agent Frameworks](https://shared.btbytes.com/p/multi-agent-frameworks), [AI Agent Framework](https://shared.btbytes.com/p/ai-agent-framework), [generative-ai](https://shared.btbytes.com/p/generative-ai), [smol-llm](https://shared.btbytes.com/p/smol-llm), transformer-math, [LlamaIndex](https://shared.btbytes.com/p/llamaindex), [RAG](https://shared.btbytes.com/p/rag), [local-llm](https://shared.btbytes.com/p/local-llm), llm-embedding, [AI SaaS](https://shared.btbytes.com/p/ai-saas), LLM Training, [Reward Models](https://shared.btbytes.com/p/reward-models), AI Code Assistants, Building LLM Based Systems, [LLMs in Data Management](https://shared.btbytes.com/p/llms-in-data-management)
- Bubeck, Chandrasekaran, Eldan, Gehrke, Horvitz, Kamar, Lee, Lee, Li, Lundberg, Nori, Palangi, Ribeiro, Zhang (2023). Sparks of Artificial General Intelligence: Early Experiments with GPT-4.
- Barrault, Chung, Meglioli, Dale, Dong, Duquenne, Elsahar, Gong, Heffernan, Hoffman, others (2023). [SeamlessM4T-Massively Multilingual \& Multimodal Machine Translation](https://arxiv.org/abs/2308.11596).
- Brown, Mann, Ryder, Subbiah, Kaplan, Dhariwal, Neelakantan, Shyam, Sastry, Askell, Agarwal, Herbert-Voss, Krueger, Henighan, Child, Ramesh, Ziegler, Wu, Winter, Hesse, Chen, Sigler, Litwin, Gray, Chess, Clark, Berner, McCandlish, Radford, Sutskever, Amodei (2020). [Language Models Are Few-Shot Learners](https://arxiv.org/abs/2005.14165).
- Eldan, Li (2023). TinyStories: How Small Can Language Models Be and Still Speak Coherent English?.
- Allen-Zhu, Li (2024). [Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws](https://arxiv.org/abs/2404.05405).
- You, Zhang, Schoop, Weers, Swearngin, Nichols, Yang, Gan (2024). [Ferret-UI: Grounded Mobile UI Understanding with Multimodal LLMs](https://arxiv.org/abs/2404.05719).
- Geiping, Goldstein (2022). [Cramming: Training a Language Model on a Single GPU in One Day](https://arxiv.org/abs/2212.14034).
- Ma, Yang, Xiong, Chen, Yu, Zhang, May, Zettlemoyer, Levy, Zhou (2024). [Megalodon: Efficient LLM Pretraining and Inference with Unlimited Context Length](https://arxiv.org/abs/2404.08801).
- Abdin, Jacobs, Awan, Aneja, Awadallah, Awadalla, Bach, Bahree, Bakhtiari, Behl, Benhaim, Bilenko, Bjorck, Bubeck, Cai, Mendes, Chen, Chaudhary, Chopra, Giorno, de Rosa, Dixon, Eldan, Iter, Goswami, Gunasekar, Haider, Hao, Hewett, Huynh, Javaheripi, Jin, Kauffmann, Karampatziakis, Kim, Khademi, Kurilenko, Lee, Lee, Li, Liang, Liu, Lin, Lin, Madan, Mitra, Modi, Nguyen, Norick, Patra, Perez-Becker, Portet, Pryzant, Qin, Radmilac, Rosset, Roy, Saarikivi, Saied, Salim, Santacroce, Shah, Shang, Sharma, Song, Ruwase, Wang, Ward, Wang, Witte, Wyatt, Xu, Xu, Yadav, Yang, Yang, Yu, Zhang, Zhang, Zhang, Zhang, Zhang, Zhang, Zhou (2024). [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://arxiv.org/abs/2404.14219).
- Lin, Hulsebos, Ma, Shankar, Zeigham, Parameswaran, Wu (2024). [Towards Accurate and Efficient Document Analytics with Large Language Models](https://arxiv.org/abs/2405.04674).
- Chollet (2019). [On the Measure of Intelligence](https://arxiv.org/abs/1911.01547).
- Ren, Liu, Lu, Shen, Liang, Chen (2024). [Samba: Simple Hybrid State Space Models for Efficient Unlimited Context Language Modeling](https://arxiv.org/abs/2406.07522).
 ## References
- [Meta Reference - letsbuild.ai](https://letsbuild.ai)
- [Keeping up with AGI](https://docs.google.com/document/u/5/d/e/2PACX-1vQD8IlBotGdBxp3BnXkSjk8bNZlPV_0EH9ZA6wHd5dNf-BLSiwXUinvgv8ZoBEnNyTCF-chWO30NRw0/pub) reading list by [cto_junior](https://x.com/cto_junior).
- [LLM Course](https://github.com/mlabonne/llm-course) by [mlabonne](https://mlabonne.github.io/blog/)
----
See also: [Multimodal Learning](https://shared.btbytes.com/p/multimodal-learning), [Multi Agent Frameworks](https://shared.btbytes.com/p/multi-agent-frameworks), [AI Agent Framework](https://shared.btbytes.com/p/ai-agent-framework), [generative-ai](https://shared.btbytes.com/p/generative-ai), [smol-llm](https://shared.btbytes.com/p/smol-llm), transformer-math, [LlamaIndex](https://shared.btbytes.com/p/llamaindex), [RAG](https://shared.btbytes.com/p/rag), [local-llm](https://shared.btbytes.com/p/local-llm), llm-embedding, [AI SaaS](https://shared.btbytes.com/p/ai-saas), LLM Training, [Reward Models](https://shared.btbytes.com/p/reward-models), AI Code Assistants, Building LLM Based Systems, [LLMs in Data Management](https://shared.btbytes.com/p/llms-in-data-management)
- Bubeck, Chandrasekaran, Eldan, Gehrke, Horvitz, Kamar, Lee, Lee, Li, Lundberg, Nori, Palangi, Ribeiro, Zhang (2023). Sparks of Artificial General Intelligence: Early Experiments with GPT-4.
- Barrault, Chung, Meglioli, Dale, Dong, Duquenne, Elsahar, Gong, Heffernan, Hoffman, others (2023). [SeamlessM4T-Massively Multilingual \& Multimodal Machine Translation](https://arxiv.org/abs/2308.11596).
- Brown, Mann, Ryder, Subbiah, Kaplan, Dhariwal, Neelakantan, Shyam, Sastry, Askell, Agarwal, Herbert-Voss, Krueger, Henighan, Child, Ramesh, Ziegler, Wu, Winter, Hesse, Chen, Sigler, Litwin, Gray, Chess, Clark, Berner, McCandlish, Radford, Sutskever, Amodei (2020). [Language Models Are Few-Shot Learners](https://arxiv.org/abs/2005.14165).
- Eldan, Li (2023). TinyStories: How Small Can Language Models Be and Still Speak Coherent English?.
- Allen-Zhu, Li (2024). [Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws](https://arxiv.org/abs/2404.05405).
- You, Zhang, Schoop, Weers, Swearngin, Nichols, Yang, Gan (2024). [Ferret-UI: Grounded Mobile UI Understanding with Multimodal LLMs](https://arxiv.org/abs/2404.05719).
- Geiping, Goldstein (2022). [Cramming: Training a Language Model on a Single GPU in One Day](https://arxiv.org/abs/2212.14034).
- Ma, Yang, Xiong, Chen, Yu, Zhang, May, Zettlemoyer, Levy, Zhou (2024). [Megalodon: Efficient LLM Pretraining and Inference with Unlimited Context Length](https://arxiv.org/abs/2404.08801).
- Abdin, Jacobs, Awan, Aneja, Awadallah, Awadalla, Bach, Bahree, Bakhtiari, Behl, Benhaim, Bilenko, Bjorck, Bubeck, Cai, Mendes, Chen, Chaudhary, Chopra, Giorno, de Rosa, Dixon, Eldan, Iter, Goswami, Gunasekar, Haider, Hao, Hewett, Huynh, Javaheripi, Jin, Kauffmann, Karampatziakis, Kim, Khademi, Kurilenko, Lee, Lee, Li, Liang, Liu, Lin, Lin, Madan, Mitra, Modi, Nguyen, Norick, Patra, Perez-Becker, Portet, Pryzant, Qin, Radmilac, Rosset, Roy, Saarikivi, Saied, Salim, Santacroce, Shah, Shang, Sharma, Song, Ruwase, Wang, Ward, Wang, Witte, Wyatt, Xu, Xu, Yadav, Yang, Yang, Yu, Zhang, Zhang, Zhang, Zhang, Zhang, Zhang, Zhou (2024). [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://arxiv.org/abs/2404.14219).
- Lin, Hulsebos, Ma, Shankar, Zeigham, Parameswaran, Wu (2024). [Towards Accurate and Efficient Document Analytics with Large Language Models](https://arxiv.org/abs/2405.04674).
- Chollet (2019). [On the Measure of Intelligence](https://arxiv.org/abs/1911.01547).
- Ren, Liu, Lu, Shen, Liang, Chen (2024). [Samba: Simple Hybrid State Space Models for Efficient Unlimited Context Language Modeling](https://arxiv.org/abs/2406.07522).